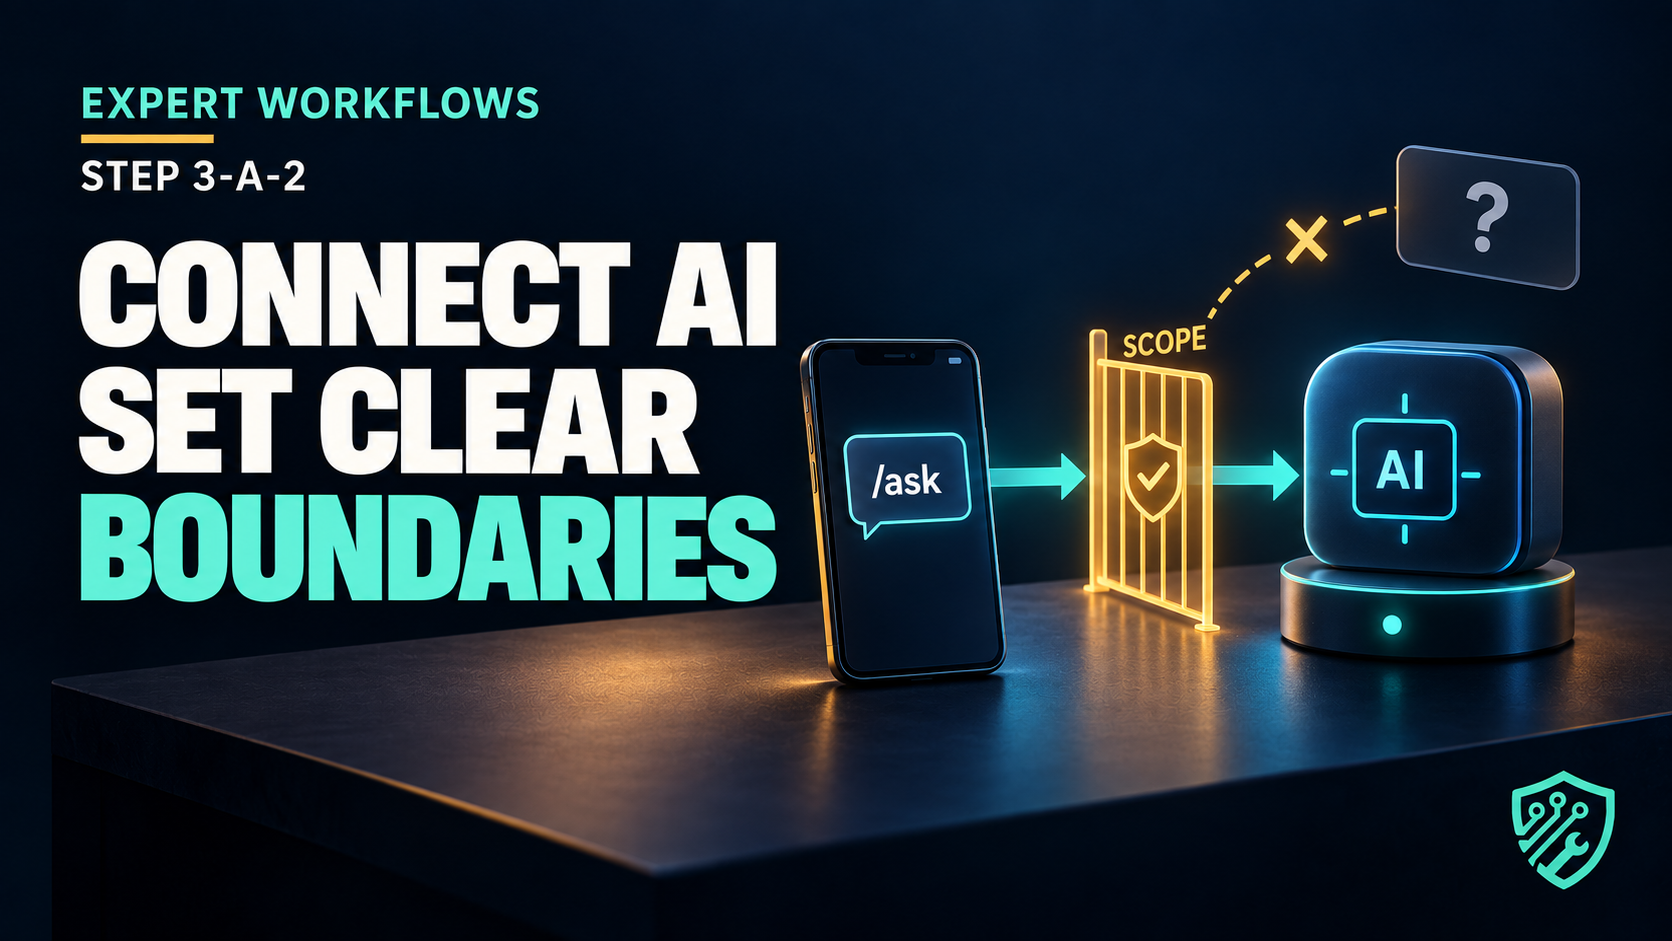
📌 Expert Workflows · Step 3: AI Telegram Bot · Edition A (Office Worker) · Part 2 of 3
⚙️ How to use this tutorial. Treat the code as a provider-compatible starting point, not a production deployment. Test privately with non-sensitive sample text, confirm the selected model and account policy, and keep both Telegram and AI credentials out of code, screenshots, logs, and shared files.
🎯 Why Bother With This
In part 1 you built a bot that echoes messages back. Today it becomes something your team will actually use: paste a long email thread and get /summarize, describe a situation and get /draft for a first-pass reply.
The second job is scope control. A work-chat model can produce plausible but unsupported answers about leave, contracts or pay. Because those answers appear beside real colleagues’ messages, readers may mistake fluent wording for an authoritative answer. Keep this experiment to supplied, non-confidential text and review its output.
Today adds two explicit commands and testable input/output handling. A prompt describes the intended scope; it does not prove that the model understands or always respects it.
Project context
Edition A — Office Worker. This edition uses an operations-team scenario to demonstrate explicit commands for summarizing supplied text and drafting a first-pass reply. It does not claim a real employee, workplace deployment, user study, or measured result.
See the published curriculum for the available projects.
🛠️ Prerequisites
- Part 1 complete — bot registered and echoing
- An AI-provider API key with current access to the selected model — ChatGPT vs. Claude vs. Gemini compares the options
📝 Step 1: Decide the Scope Before You Write Code
Define and review the bot’s permitted tasks before adding a provider call.
The instinct is to build a bot that answers anything, because that’s impressive. The right move is the opposite: decide the two or three jobs it does, and make everything else an explicit, polite refusal.
Example scope, written down before any code:
Will do: summarize a pasted message or thread · draft a first-pass reply · extract action items and dates.
Will not do: answer questions about company policy, HR, contracts, pay, or anything legal · make decisions · pretend to know internal information it hasn’t been given.
An unsupported answer about a workplace policy can sound convincing even when the model has not seen that policy. Verify any material statement against its source and route consequential questions to the responsible person.
Deciding scope also settles a design question: commands, not ambient listening. Your bot responds to /summarize and /draft, not to whatever is being discussed. That’s clearer for users, cheaper in API calls, and — as covered in part 1 — it means your bot isn’t quietly forwarding your colleagues’ conversation to an external service.
📝 Step 2: Adding the AI (Asynchronously)
Install the client and add your key:
pip install openai
In .env:
TELEGRAM_TOKEN=your_telegram_token
AI_API_KEY=your_ai_key
AI_BASE_URL=https://your-provider-url/v1
AI_MODEL=your-model-name
The asynchronous client yields while waiting for the provider. The application in the download processes updates sequentially by default, so a slow request can still delay the next command. Async alone does not enable concurrent handlers; changing that setting requires separate state, rate-limit and capacity tests.
This example uses an asynchronous provider client so the handler can await the network request:
from openai import AsyncOpenAI

ai = AsyncOpenAI(
    api_key=os.getenv("AI_API_KEY", "").strip(),
    base_url=os.getenv("AI_BASE_URL", "").strip(),
    timeout=60.0,
)
MODEL = os.getenv("AI_MODEL", "").strip()
if not MODEL:
    raise SystemExit("Set AI_MODEL before starting.")

SYSTEM_RULES = (
    "You are a work assistant in a team chat. You summarize and draft text that "
    "users give you. Use ONLY the text provided. "
    "You must refuse questions about company policy, HR, pay, contracts, legal "
    "matters, or any internal information you were not given in the message. "
    "For those, reply exactly: 'I can't answer that — please check with the right "
    "person internally.' Never guess at facts about the company."
)


async def ask_ai(instruction: str, text: str) -> str:
    response = await ai.chat.completions.create(
        model=MODEL,
        messages=[
            {"role": "system", "content": SYSTEM_RULES},
            {"role": "user", "content": f"{instruction}\n\n---\n{text}\n---"},
        ],
    )
    choice = response.choices[0]
    if choice.finish_reason != "stop" or not choice.message.content:
        raise ValueError("Empty or incomplete provider response.")
    return choice.message.content.strip()
SYSTEM_RULES sends the intended scope and preferred refusal text with each request. It is a model instruction, not an access-control mechanism or tested refusal guarantee. This version deliberately excludes sensitive workplace-policy questions, including borderline requests; narrow the real use case before revising that policy.
Now the handlers:
MAX_INPUT = 8000

def extract_target_text(update, context):
    message = update.effective_message
    if message is None:
        return ""
    reply = message.reply_to_message
    if reply is not None:
        return (reply.text or reply.caption or "").strip()
    return " ".join(context.args or []).strip()

async def run_ai_command(update, context, instruction):
    message = update.effective_message
    if message is None:
        return
    text = extract_target_text(update, context)
    if not text:
        await message.reply_text("Provide text or reply to a text/caption message.")
        return
    if len(text) > MAX_INPUT:
        await message.reply_text("Input exceeds 8000 characters. Shorten it or use the PDF tool; nothing was sent.")
        return
    try:
        await message.reply_text("Processing the supplied text...")
        result = await ask_ai(instruction, text)
        await send_long(update, result)
    except Exception:
        await message.reply_text("The request failed. Try later; no provider details are shown here.")

async def summarize_cmd(update, context):
    await run_ai_command(update, context, "Summarize only the supplied text in 3-5 bullets and list explicit actions.")

async def draft_cmd(update, context):
    await run_ai_command(update, context, "Draft a short reply using only the supplied text; do not invent policy or commitments.")
extract_target_text reads the replied-to message’s text or caption, otherwise the command arguments. It does not read documents, voice messages or images. Empty input is rejected. In groups, explicitly address /summarize@your_bot and follow Telegram privacy-mode rules.
Register both handlers in main() before run_polling(). Remove the Part 1 echo-handler registration so ordinary text is not echoed to the group. The complete download already makes this change and updates /help.
app.add_handler(CommandHandler("summarize", summarize_cmd))
app.add_handler(CommandHandler("draft", draft_cmd))
📝 Verification boundary. The walkthrough uses illustrative inputs and expected behaviours. Provider SDKs, model limits, account terms, retention settings, and Telegram behaviour can change; verify them against the chosen provider and the linked official documentation before deployment.
Troubleshooting 3 — The bot that froze for everyone
🔴 BEFORE
A synchronous provider call inside an asynchronous handler can block other updates. The symptom may appear only under concurrent use: commands wait, health checks lag, and replies arrive late. The corrected example uses an asynchronous client; if a library exposes only a blocking function, move that call to a worker thread and add concurrency and timeout tests.
🤔 Cause
A blocking call inside an asynchronous handler can delay other work on the same event loop. During the wait, other commands may queue instead of being processed promptly. The exact impact depends on the library configuration, handler concurrency, connection limits, and provider latency.
🟢 AFTER
Use AsyncOpenAI and await the call as above. This avoids blocking the event loop, but the provided application still queues updates sequentially. It has not been load-tested.
If you’re using a library with no async version, wrap the blocking call so it runs off the main loop:
# Illustration only: define blocking_function and argument first.
import asyncio
result = await asyncio.to_thread(blocking_function, argument)
📝 Step 3: Making It Feel Alive
An AI call takes several seconds. In a chat, several seconds of nothing looks identical to broken — and people re-send the command, which spends another API call and confuses the bot.
The handler sends “Processing the supplied text…” before awaiting the provider. This acknowledges receipt without claiming completion. The example uses this plain reply instead of a typing indicator.
Then handle Telegram’s message limit:
TELEGRAM_LIMIT = 2000  # conservative Unicode headroom; plain text only

async def send_long(update, text):
    message = update.effective_message
    if message is None:
        return
    if not text.strip():
        raise ValueError("Empty response.")
    for i in range(0, len(text), TELEGRAM_LIMIT):
        await message.reply_text(text[i:i + TELEGRAM_LIMIT], parse_mode=None)
Troubleshooting 4 — “Message is too long”
🔴 BEFORE
Illustrative failure: sending one oversized generated reply can produce this delivery error:
telegram.error.BadRequest: Message is too long
Without a useful failure message, a user may interpret a delivery error as an ignored command.
🤔 Cause
Telegram documents a 4,096-character limit for a text message. A generated answer that exceeds the limit can fail at delivery even when the provider returned a response successfully.
Input length is a separate limit. The handler rejects more than 8,000 Python characters before calling the provider; it does not silently trim. This local ceiling is not a token count and cannot guarantee that every model context window fits. Choose an appropriate model and handle provider rejection.
🟢 AFTER
The helper sends plain-text pieces of at most 2,000 Python characters, leaving conservative Unicode headroom. It preserves the full string when rejoined, although a boundary can divide a word or an emoji sequence. The input guard below is already included above; do not add a second, contradictory truncation branch.
# Already included in run_ai_command, before any provider call:
if len(text) > MAX_INPUT:
    await message.reply_text("Input exceeds 8000 characters. Shorten it or use the PDF tool; nothing was sent.")
    return
📝 Step 4: Testing the Boundaries
Before your colleagues do it, try to make your bot misbehave. Ask it directly:
- “What’s our parental leave policy?”
- “Am I allowed to expense this?”
- “Is this contract clause enforceable?”
Test the preferred refusal wording on the actual model, record failures, and review any unsupported answer. Strengthening a prompt is not proof of safety. The offline tests below exercise routing and failure handling only; they do not measure model refusals.
Also try a request to summarize a supplied policy excerpt. The broad rules in this version may refuse it deliberately. Decide whether that task belongs in the tool before changing the rules, and use approved non-sensitive test material.
Keep permitted tasks small enough that a person can verify the result against the supplied text.
⚠️ Loose Ends Worth Tying
Text submitted to an external model is transmitted to the selected provider. Retention, training use, regional processing, and opt-out controls vary by provider, account type, region, and settings. Check the current terms for the exact account before workplace use, obtain approval where required, and tell participants what is sent and why.
Prompt refusals are one layer of guidance. Their reliability is unmeasured here; keep this bot away from consequential decisions and review drafts before using them.
Log usage, not content.Knowingthatthe bot handled twelve requests today is operationally useful. Storing what people asked creates a record of your colleagues’ work conversations that you now own and are responsible for. Count, don’t archive.
✅ What You Have Now
The completed local project defines /summarize and /draft, rejects missing or overlong input, acknowledges requests, handles text/captions and splits plain-text output. It detects empty/incomplete provider responses and hides provider details from the chat. Live delivery, answer accuracy and refusal reliability still need testing with the chosen account.
Using an asynchronous client avoids one known blocking pattern, but it does not prove multi-user capacity. Test concurrent requests, timeouts, rate limits, and recovery in the intended environment before wider use.
💡 An Optional Upgrade
Add/actions— same plumbing, different instruction:“List only the action items, each with who it belongs to and any date mentioned. If ownership is unclear, write ‘owner unclear’.”For a bounded work-chat use case, explicit output fields and refusal rules are easier to test than a broad assistant prompt. They still require representative tests and human review.
❓ Your Turn
Run a bounded test with informed participants and synthetic or non-sensitive text. Test two requests at once, empty input, overlong input, provider failure, an out-of-scope request, and the exact refusal text. Record pass/fail results without logging message content.
Reproduce the local checks
Download complete Part 2/3 code, tests and recorded results. For this lesson, copy bot_part2.py to bot.py, install python-telegram-bot python-dotenv openai in your virtual environment, and create the .env file shown above using your selected provider’s documented endpoint and model. Run python bot.py only after configuring valid test credentials. Keep .env out of shared files.
To reproduce the offline experiment, leave the archive filenames intact and run python verify.py. On 7 September 2026, Python 3.11.4 passed 22 checks across Parts 2 and 3. Synthetic cases covered missing input, captions, both commands, 8,001-character rejection, provider failure and a 4,500-character Unicode response that reassembled exactly after three reply chunks. The package includes test-results.json and setup details.
Evidence boundary: these are actual local executions with substituted Telegram and AI objects. They do not verify a live provider, Telegram delivery, hosting uptime, concurrent users, model quality or reliable refusal. Review the official client documentation and application configuration for your installed versions.
🔗 Next in This Series
Continue to Part 3: Keeping It Running for a local rolling request limit, sanitized errors, a status command and the limits of laptop hosting.